Below, who is running faster.
GPT-5.6 Sol Ultrafast mode · powered by Cerebras · 14x speedup
OpenAI partnered with Cerebras to preview Ultrafast mode: flagship model GPT-5.6 Sol runs up to 14 times faster than Standard mode, with output reaching 750 tokens per second.
This is not a new model; it is the existing strongest model made much faster. What does 750 tok/s mean? The Standard baseline sits at about 53 tok/s. Per Artificial Analysis, Ultrafast is 11x faster than Fable 5 and 5x faster than Opus 4.8 Fast, with no quality loss claimed. Enterprise customers get the same model with response times dropping from seconds to fractions of a second.
The target is real-time scenarios: voice conversation, customer service, e-commerce recommendations, coding assistance, financial research, security response. In these, speed is the experience, and the experience is money. The compute comes from Cerebras' wafer-scale chips: beyond Nvidia, the compute landscape has gained its first officially certified alternative name.
Who is Cerebras? A wafer-scale chip company that turns an entire wafer into one chip, specialized in inference acceleration, previously serving medical and research institutions. Being chosen by OpenAI as the official compute base for Ultrafast hands it an entrance ticket to the "frontier model inference" race. For Nvidia, this is the first time someone has taken a share of "official recommendation for top models".
Enterprise customers can do the math: the same GPT-5.6 Sol going from 53 to 750 tok/s means more multi-turn interactions in one window, longer context processing, faster agent feedback. For real-time product teams this is not "a bit faster"; it is the difference between "possible" and "impossible". Product shapes that latency ruled out now have a path.
As gaps in model capability narrow, "who returns results first" becomes the new dividing line. OpenAI did not train a stronger model; it ran a faster one first, and speed has become its answer to "too expensive".
Databricks officially closed a $5B strategic round at a $190B post-money valuation, up about 42% from February's $134B. Coatue led, with Blackstone, MGX and T. Rowe Price participating.
CEO Ali Ghodsi told TechCrunch: "AI is expensive." The round was originally planned at $1B, but investors pushed $15B in, settling at $5B. Why refuse more? To avoid over-dilution, and because the company does not need it: annualized revenue has passed $7B, Q2 grew over 80% year-on-year, and the AI data product Lakebase passed $100M annualized.
"Wanted $1B, got offered $15B": the gap itself is the signal. Money is chasing AI infrastructure. Databricks positions itself as "the data layer of the AI era", and investors are betting on the data entrance for the next decade. When a round can expand from $1B to $5B and still feel small, capital is inflating, and inflated capital will eventually lift the price of every AI asset.
Zoom out: Databricks was valued at $62B in December 2025, $134B in February 2026, $190B now, tripled in about half a year. Why the frenzy? Because "the data layer of the AI era" is a highly certain story: models can be swapped, apps can be swapped, but enterprise data ultimately needs somewhere manageable, queryable and feedable to AI. That entrance is what Databricks is betting on.
Compare peers: Snowflake also builds an AI data platform at roughly an $80B valuation; Databricks at $190B is nearly double. The gap comes from execution: from lakehouse to Lakebase real-time AI data, Databricks binds "data" and "AI" tighter. When model capabilities converge, whoever's underlying data is cleaner and more real-time holds the negotiating leverage.
A 42% valuation jump in six months while annualized revenue already runs $7B: money for the AI data layer has moved from "should we invest" to "fighting to get in".
Databricks fundraising.
Cursor announced that the Firetiger team is joining, a classic acqui-hire: Firetiger's standalone product will shut down and its technology merges into Cursor.
Firetiger was founded by two ex-Cloudflare/Twitch engineers, Rustam Lalkaka and Achille Roussel, had raised a $7.6M seed round led by Sequoia, and built production-environment AI agents that monitor releases, catch regressions and investigate incidents: "Change Monitors". Post-acquisition, this folds into Cursor's Origin platform, completing the chain from writing code to running in production.
Why Cursor? Over the past year Cursor has pivoted from "AI editor" to "agent platform": Origin lets AI run tasks independently; Change Monitors let AI watch production. Firetiger's monitoring and regression-catching fills the "after the code is written" gap. Write code, ship it, catch problems automatically: Cursor wants the whole loop.
For the developer community it is another signal: competition among coding tools has moved from "whose completions are better" to "who can let AI own a project end to end". GitHub Copilot builds workspace agents; Cursor acquires agent teams. Terminal products are eating mid-layer startups, and Firetiger will not be the last.
The cost falls on paying customers: Firetiger stopped new signups, existing customers received termination notices, and data will be deleted. Top agent talent has become expensive enough that buying beats hiring, and behind every acqui-hire stands a group of users being "merged away".
Firetiger team joins Cursor.
Writer released a new flagship, Palmyra X6, post-trained on Beijing-based Z.ai's open-source GLM-5.2: a 744B-parameter MoE with about 40B active parameters per token.
Look deeper and Writer's play is a template for "commercializing open models": Z.ai open-sourced GLM-5.2, Writer post-trained it into its flagship. Open models' general capability caught up with closed ones in 2026, creating room for "second-development" companies. Similar plays include Together and Fireworks, both building enterprise customization on open foundations.
For closed vendors like Claude and GPT this is pressure: when "open weights plus fine-tuning" delivers 90% of the effect at one-fifth the price, enterprise budgets start splitting. Writer's average evaluation score of 0.87 edges past Opus 4.8's 0.86; the sample is limited, but "good enough and cheap" is becoming the new procurement standard. The best does not win; the best value does.
"Saving money" has turned from an ops metric into a product pitch. AI has entered its thrifty era: whoever saves enterprises money first wins the budget.
MiniMax released Music 3.0 weights on Hugging Face (MiniMaxAI/MiniMax-Music3), with ComfyUI 0.33 adding native support the same day. Official words: "We will keep everything open source until AGI arrives."
On paper it is a multi-module model: an 8B global LLM (initialized from Qwen3.5-8B) plus a 0.6B local LLM plus a 2.4B flow-matching module plus a 123M Flow-VAE, generating full songs up to 5 minutes in 32kHz stereo. The API version shipped in July; this release opens the weights. Running locally means no uploads, no queues, no per-track fees: creators can finally own their AI scoring tool.
The ecological niche of open music models is subtle: closed products like Suno and Udio dominate, while open source previously had only small models. Music 3's architecture puts "five-minute full songs" within local reach, and with ComfyUI workflows an ordinary creator can assemble a complete AI music pipeline on their own machine.
MiniMax's logic is open source in exchange for ecosystem: from H2 to Music 3 it keeps open-sourcing flagship capabilities, feeding its brand through the developer ecosystem. Against Suno's subscription model, the open route bets on the flywheel of more users leading to more improvements leading to faster iteration. For creators, it is optionality: those who dislike per-track fees or uploading data can just run it locally.
When Chinese companies' open source spreads from "model parameters" to "creative tools", the battlefield widens past developers to every creator.
Alibaba released Qwen3.8-Max open weights: 2.4T total / 95B active MoE with only about 4% activation, priced at $2/$6 per million tokens via API. Community verdict: "one of the largest open-weight releases ever".
Third-party evaluations are strong: Frontend Code Arena #4 (Elo 1668, behind only Claude Opus 5 and Kimi K3), Vision Arena #2 (1305, 13 points from Claude Fable); Vals composite index 66.1, second among open models and tenth of all 43; SWE-bench 87.3%, ahead of GPT-5.5 (82.6%) and GLM-5.2 (83.3%). More valuable is the improvement curve: Vals rose from 3.7 Max's 57.5 to 66.1, an 8.6-point gain in two and a half months, while prices fell from $2.5/$7.5 to $2/$6.
The ecosystem was ready on day one: vLLM day-0 support plus dedicated 4-bit quantizations for NVIDIA B300 and AMD MI355X; Together and Baseten could run it immediately. But Jamin Ball poured cold water: K3 alone needs over 1TB of memory to load weights, at least 8 H100s; open weights do not mean locally runnable. The initial release is also text-only, vision not yet unlocked, and license terms appear to restrict downloads from the US, EU, UK and Korea, unclarified by Alibaba at press time.
When a 2.4T open model scores near closed flagships at a fraction of the price, "the gap between open and closed" becomes "who can actually run it".
Qwen3.8-Max open weights.
Google released Gemini 3.7 Flash just three weeks after 3.6 Flash: 1M-token context, 64K output, WebDev Arena Elo of 1588, API pricing at $0.75 per million input tokens (rising to $1.50 from 2027).
The eye-catcher in the official demos is 3D generation: a usable 3D watch model from one sentence, at about $0.038, under four cents. 3D modeling used to be billed by the designer-hour; now it is one sentence plus four cents. When generation cost becomes negligible, "can you model" stops being the barrier and "do you want to make it" becomes the question.
Watch the iteration cadence even more than the features: only three weeks between 3.6 and 3.7. Google is compressing releases from quarterly to monthly, and the Flash line has become the fast lane for trialing new capabilities: cheap, quick to iterate, steadily gaining abilities. The same event added the Nano Banana image model and Gemini Omni, completing a full product matrix.
For developers the direct implication: capability grows by the month, so vendor choices must be remade by the month. Last quarter's optimum may already be displaced by a cheaper new version.
The collapse of 3D content production cost may cut deeper than image generation did, because 3D is the foundation of manufacturing, games and e-commerce, and it is turning into a sentence: "make me one of these".
OpenAI introduced Computer History in ChatGPT for Mac desktop, replacing the screenshot-based Chronicle research preview. It targets Pro, Business and Enterprise users, is off by default, and requires admin authorization on enterprise plans.
How it works: instead of screenshots, it uses macOS accessibility APIs to record clicks, keystrokes, shortcuts and app switches, producing memories and timelines that ChatGPT/Codex can reference. Events upload to servers to generate memories; OpenAI says they are not retained after processing and not used for training. Interaction events stay local for up to 48 hours; the first rollout excludes the EEA, Switzerland and the UK.
Why it matters: this is the first step from "AI remembers what you said" to "AI remembers what you did" at screen level. Before, AI remembered your conversations; now it remembers your actions. For agent scenarios that is a qualitative change: ChatGPT can pick up where your last browser session left off, without you re-explaining context.
Media reaction was blunt: The Register called it "a friendly keylogger". It improves personalization but raises token consumption and prompt-injection risk, which OpenAI's own docs acknowledge, suggesting pausing it when others' communications are involved. Critics note prompt injection can poison long-term context through this memory channel.
When AI starts recording your screen, users usually click "agree" before reading the terms of the convenience-for-privacy trade. This time, the terms read "keylogger".
ChatGPT launches "Computer History".
Suno released Studio 2.0, adding MIDI import/recording/editing (usable as generation prompts), a dual-oscillator wavetable synthesizer, track automation curves and built-in effects (distortion, delay, reverb, compression, EQ), available to Premier users the same day.
The most notable update is the Chat panel: custom plugins can be created in natural language, free of credits during launch. AI music tools are turning "mixing" into conversation too. Premier users get unlimited 32-bit/48kHz multitrack and stem exports, with advanced stem separation also arriving.
Suno says MIDI was Studio's most requested feature, and 2.0 was built on a year of user feedback, aiming to upgrade Studio from "simple AI editor" to "full DAW-style production environment". What does MIDI change? You can import a melody you played yourself and have AI arrange on top of it: human-AI collaboration moves from "giving a sentence" to "giving a real performance".
The creator tiers are clear: Pro users refine with the new synths and effects; Premier users take unlimited multitrack exports into commercial-grade mixing. Competition among AI music tools is shifting from "who generates longer songs" to "who plugs into professional workflows", and DAW-grade capability is the dividing line.
When AI music starts benchmarking against professional production tools, inspiration-to-finished-track compresses to minutes. Writing melodies stops being scarce; conducting AI becomes the skill.
Suno Studio 2.0: AI music goes professional DAW-style.
Image: Suno official.
Anthropic signed a 20-year compute lease (through June 2048) with bitcoin miner Riot Platforms: 191 MW of critical IT capacity, about $9.1B in initial contract revenue, up to $16.1B with two five-year extensions.
The deal details are hardcore: Riot's Texas facility delivers 96 MW in December 2027 and the remaining 95 MW by June 2028; Morgan Stanley provides bridge financing; AMD is another tenant in the same park. The mining farm is becoming an AI compute campus.
Why buy power from miners? Mining sites have industrial power, cooling and land ready-made; converting them to AI data centers costs far less than building new. Anthropic spent $6B on acquisitions while locking $9.1B of compute: competition among top labs has become capital lock-up measured in decades.
The AI arms race has shifted from "who is stronger" to "who locks up resources first", and this time the lock is on Texas electricity through 2048.
Anthropic locks in 20 years of compute.
"Zuckerberg wrote 6,500 words of AI manifesto, and said almost nothing."
— Wired review · Zuckerberg AI Manifesto · Wired
"AI is expensive."
— Ali Ghodsi · Databricks CEO, on wanting to raise $1B and taking $5B instead · TechCrunch
Today's keyword was "fast": models sped up 14-fold, one sentence yields a 3D model, and AI music went commercial.
Money chased too: hoping for $1B, Databricks took $15B, and the data layer's valuation climbed to $190B.
Once capability is good enough, speed, cost and barriers become the starting line of the next race.
The Sargassum Belt, Atlantic Ocean — NASA's satellite captured a floating algae belt spanning the ocean, like a river that breathes.
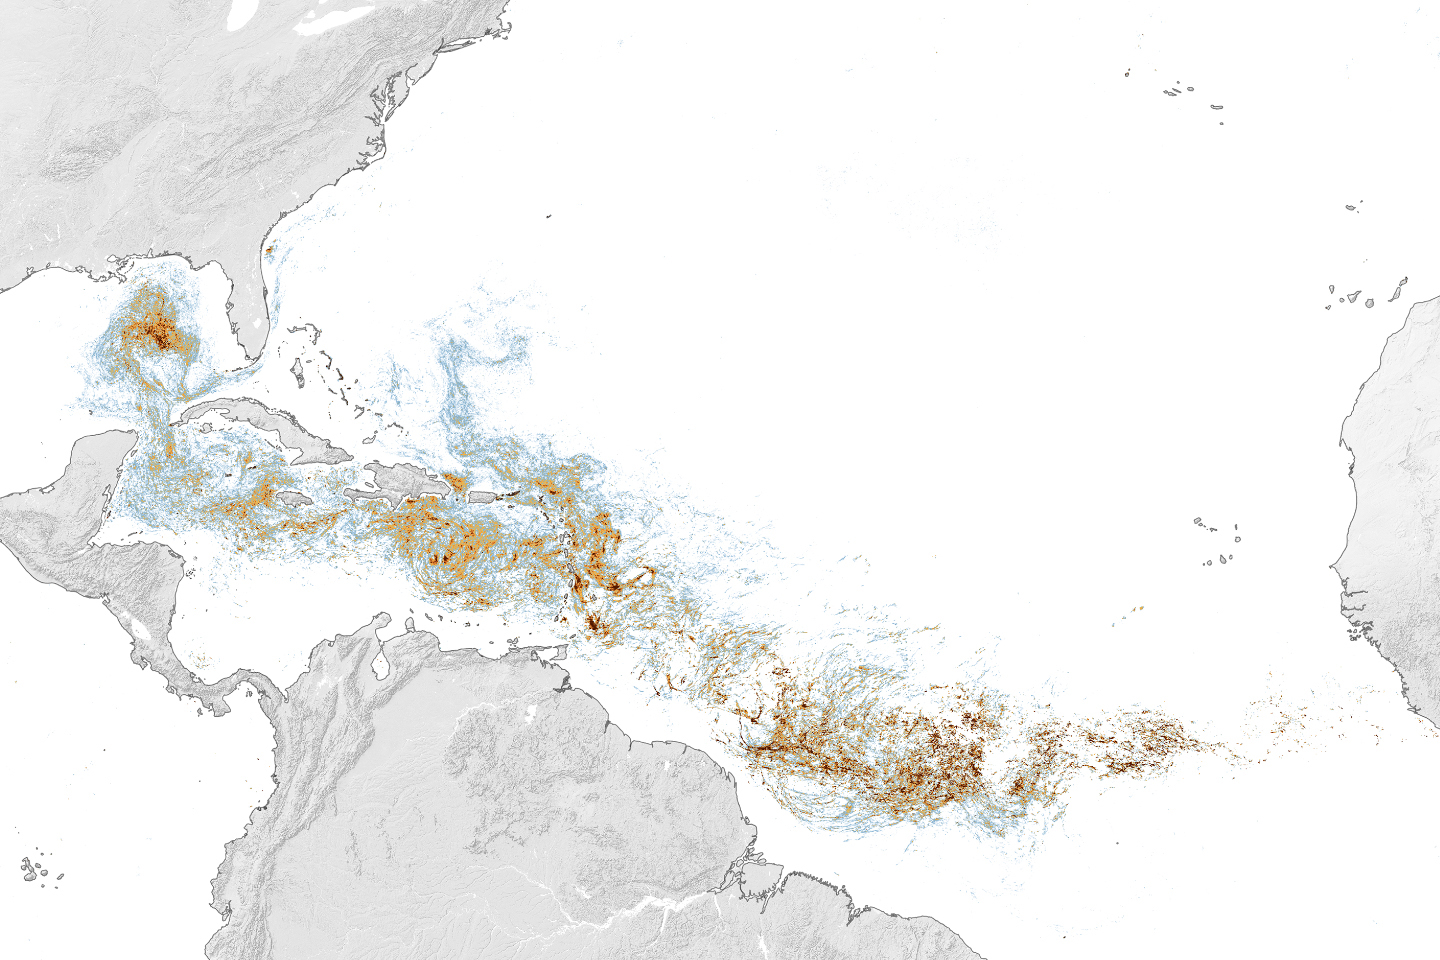
Sargassum Belt · Atlantic Ocean · photographed by NASA · 15.0°N, 45.0°W
This algae belt stretches across the Atlantic, thousands of kilometers at its widest. No company feeds it; sunlight and currents alone grow it into a "floating forest". While we argue on screens about who sped up 14-fold and whose valuation hit $190B, this belt follows the ocean's rhythm, deciding where to drift this year and which shores to reach. After a day of AI news, Earth still has places that need no GPU cooling. Mountains and seas — stay curious, keep exploring.