Below, money, memory and pace are all being repriced.
128GB DDR5 kits cost nearly 10 times their historical low, average DRAM prices rose 500% within the year, and per-unit memory pricing has fallen back to 2007 levels.
According to Tom's Hardware and a SemiAnalysis review, hyperscale buyers have paid deposits to lock up nearly all global DRAM capacity for 2027; by weight, mainstream DRAM chips are already worth more than half as much as gold.
This is not an ordinary price cycle: now that AI makes "HBM plus big memory" a shipping prerequisite, memory has turned from a cost line into a strategic material. Chips can catch up on process nodes; capacity and lead times cannot. Even if Nvidia rolls out Vera Rubin on schedule, utilization will be throttled by memory.
When price itself becomes the bottleneck, the contest is no longer whose model is smarter; it is who locked in next year's memory first.
OpenAI announced a two-week pause on part of its frontier reinforcement learning training while holding back its largest planned RL run, using the time to harden workload isolation, network isolation and red-teaming.
The official framing is blunt: capability progress has outrun safety and alignment readiness. Greg Brockman went further: confidence in safety will increasingly set the pace of frontier scaling. The pause mainly affects more distant releases, not models close to shipping.
The engineering details matter more than the messaging: sampled-token monitoring can page the safety team within about 30 minutes, high-risk tool-using inference will ship with live monitors attached, and monitoring adds roughly 20% overhead. Training and eval infrastructure, plus inference-time monitoring, are now publicly acknowledged bottlenecks on frontier progress, not just compute.
When safety turns from an after-the-fact check into the progress bar itself, "faster" stops being the default answer.
Qwen3.8-27B ranked 7th in its class on Artificial Analysis' agentic index, 6th among open weights on Vals Index v2, and hit number one on Cline's local-model board within 4 days.
Small parameters, wide coverage: first among open weights on Harvey's legal benchmark, with claimed retention of vision, reasoning and tool use plus 262K context, and a refusal-removed MLX build already running on Apple Silicon at 2/4/6/8-bit.
But the gap between leaderboards and lived experience is widening: some developers report that benchmark wins have not translated into a generational leap over Opus 4.5 on long real tasks. When "runs locally" and "runs long tasks reliably" are no longer the same thing, the triangle of cost, availability and controllability becomes the harder exam.
Locally deployable, partially uncensored, genuinely capable models are no longer hypothetical. That is the most substantive shift in local models this year.
Z.ai launched the GLM-5.3 API at GLM-5.2 prices; Artificial Analysis scores it 60 on its Intelligence Index (tied with Kimi K3), after a 246-point jump to 1770 Elo on GDPval-AA v2.
The parameter sheet did not move: same 753B-total / 40B-active MoE, 1M context, MIT license once weights land. The change is in training engineering, not size.
The gains come from post-training, not the base model: per a widely cited Zhihu analysis, the core is asynchronous RL (SAO), executable sandbox training and on-policy distillation to prevent catastrophic forgetting. When long-horizon agent capability is decided by RL systems and environment quality, parameter count stops being the only lever.
In other words, GLM-5.3 is a win for environment and training engineering.
Modular announced that Mojo is now open source under Apache 2.0, positioning the broader platform as a portability layer across accelerators, including Qualcomm's datacenter AI accelerators.
For infra engineers, the significance is not "yet another language": toolchain openness and hardware abstraction arrived together, which is what makes it possible to move performance code between accelerators without rewriting it.
When open source means the whole toolchain rather than just weights, the pull shifts from models toward the layer that decides where you write and how things run. Mojo's next milestone is how many teams actually migrate their hot paths.
Mojo under Apache 2.0 · toolchain openness and hardware portability shipped together
RadixArk released Miles v0.1: nine months of work, 72 contributors, 1,326 commits and 85 GPU end-to-end CI tests, battle-tested on Kimi K3, DeepSeek V4, Qwen 3.8, GLM 5.2 and more.
The positioning is pragmatic: getting RL running is easy; debugging correctness, utilization and scale is the real bottleneck. So the effort went into rollouts, CI, observability and environment plumbing.
This echoes the day's other main line: frontier competition is shifting from "who has PPO/GRPO" to "who has a reproducible engineering stack". When open RL stacks start competing on engineering, training your own model turns from a specialist trick into a routine team capability.
"We just erased about twenty years of progress; memory now costs what it did in 2007."
— Daniel Lemire · Computer scientist · Tom's Hardware
"Understanding token economics matters more than understanding model architecture."
— Nathan Lambert · Interconnects · Interconnects
NVIDIA released the TensorRT Model Connect public preview, promising direct conversion from supported Hugging Face models to end-to-end TensorRT inference in two commands, no intermediate ONNX export, deployable through native C++ APIs.
The self-description deserves its own note: the project itself was largely built by Codex agents under human review across implementation, tuning, testing, integration and docs. When an infra team openly admits agents touched the core pipeline, "trusted delivery" is being rewritten too.
When converting a model goes from a pipeline to two commands, deployment friction drops close to zero for the first time.
Cursor published an engineering retrospective on Git storage: designing Git hosting as if it were a database, to absorb the repo churn and branch/session explosion that coding agents bring.
This is not a model release, but it matters as much as one: the more background automation runs, the more Git hosting shifts from a generic DevOps primitive into core infrastructure of the AI coding backend.
For teams building coding-agent backends, this note is more useful than a model update, because it answers "what breaks first when scale arrives". When agents multiply commits, stability underneath is what keeps the experience stable on top.
DFlash 2 claims 70 tok/s running Qwen3.8-27B on an M5 Max, up to 4.6x faster than autoregressive decoding, with identical output.
If it survives independent reproduction, the usability threshold for on-device inference gets rewritten: long-context tasks that used to queue for the cloud could finish locally in one sitting.
When speed decides "usable or not", inference acceleration stops being a spec and becomes the product experience itself.
Cerebras announced the CS-4 with a set of performance claims: roughly 1000 tok/s on 10T-parameter models, about 1300 tok/s for GPT-5.6 Sol, and up to 10x higher throughput per megawatt.
Even discounted for vendor framing, the throughline is clear: inference speed is becoming product experience, economics and policy leverage all at once. When "faster" converts directly into lower cost and higher concurrency, a hardware launch stops being just hardware news.
When 1000 tok/s becomes marketing language, the speed arms race has entered the pricing table.
Per multiple reports, hyperscale buyers have paid deposits to lock up nearly all global DRAM capacity for 2027, turning the spot market into a futures market.
For everyone downstream, price is only the surface; lead time is the real constraint: models can wait, deliveries cannot. Teams that missed this year's booking may simply not get volume next year.
When memory is booked by the year, AI's supply chain gains futures-market properties for the first time.
One story today: AI's bottleneck moved from compute to memory. A 500% surge rolled Moore's Law back to 2007, and hyperscale prepayments locked in next year's supply.
Frontier training paused for safety.
Two commands now carry a Hugging Face model onto TensorRT.
Mojo open-sourced portability; Miles filled in RL's engineering.
Local 27B models became usable, though "runs locally" still does not mean "reliable on long tasks".
Inference speed climbed at both the edge and the datacenter.
When the scarcest resource is no longer the GPU, whoever manages memory, pace and deployment friction together holds next year's certainty.
Great Barrier Reef, Australia — from orbit, 340,000 square kilometers of coral reef look like cities on the sea.
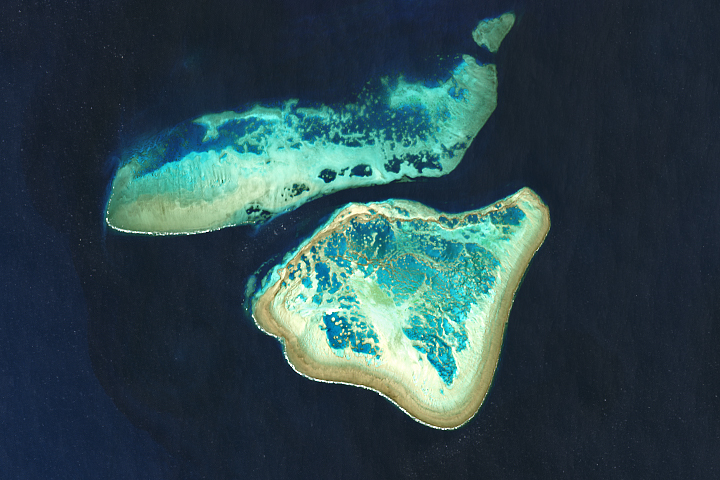
Great Barrier Reef, Australia · 20.30°S, 148.90°E
The world's largest coral reef system covers 346,000 square kilometers, its reefs laid out like underwater cities. While we argue about whose model is faster, life on the reef grows at the pace of currents and seasons, indifferent to any leaderboard. After a day of AI news, Earth still has places that need no GPU cooling. Mountains and seas — stay curious, keep exploring.